Pixmo
PixMo is a comprehensive multimodal dataset designed to enhance vision-language understanding. It comprises seven distinct datasets, three with human annotations and four generated synthetically covering detailed image captions for pre-training, free-form image-based question answering for fine-tuning, and a novel 2D pointing dataset. Notably, all data was collected without relying on external vision-language models (VLMs). The following table describes these datasets and data collection methods.
| Sub-Dataset | Description | Size | Type |
|---|---|---|---|
| PixMo-Cap | High-quality, dense captions from ∼70 diverse topics. Human annotators verbally described images which was transcribed via speech-to-text and refined by an LLM. | 712k captions, 1.3M transcripts (avg. 196 words) | Human-annotated |
| PixMo-AskModelAnything | Image-question-answer triplets created via human prompts, OCR output, and PixMo-Cap captions, refined using a language-only LLM with annotator approval. | 73k images, 162k QA pairs | Human-annotated |
| PixMo-Points | Pointing annotations for item identification, counting, and explanations. Includes negative samples ("not present") and chain-of-thought point sequences. | 223k images, 2.3M question-points, 79k explanations | Human-annotated |
| PixMo-CapQA | QA pairs generated by prompting a language-only LLM using only the image’s ground-truth caption. | 165k images, 214k QA pairs | Synthetic |
| PixMo-Docs | QA pairs generated by LLM using privileged access to image-generating code (charts, documents, tables, diagrams). | 255k images, 2.3M QA pairs | Synthetic |
| PixMo-Clocks | Synthetic clock images with corresponding time-telling QA pairs. Includes varied watch faces and times. | 826k examples | Synthetic |
| PixMo-Count | Counting QA pairs generated using object detectors on web images, validated on counts 2–10. Includes training set with object center points and QA. | 36k train images, 540 val/test images | Synthetic |
PixMo dataset examples
The following examples illustrate the diversity and annotation depth across PixMo’s sub-datasets.
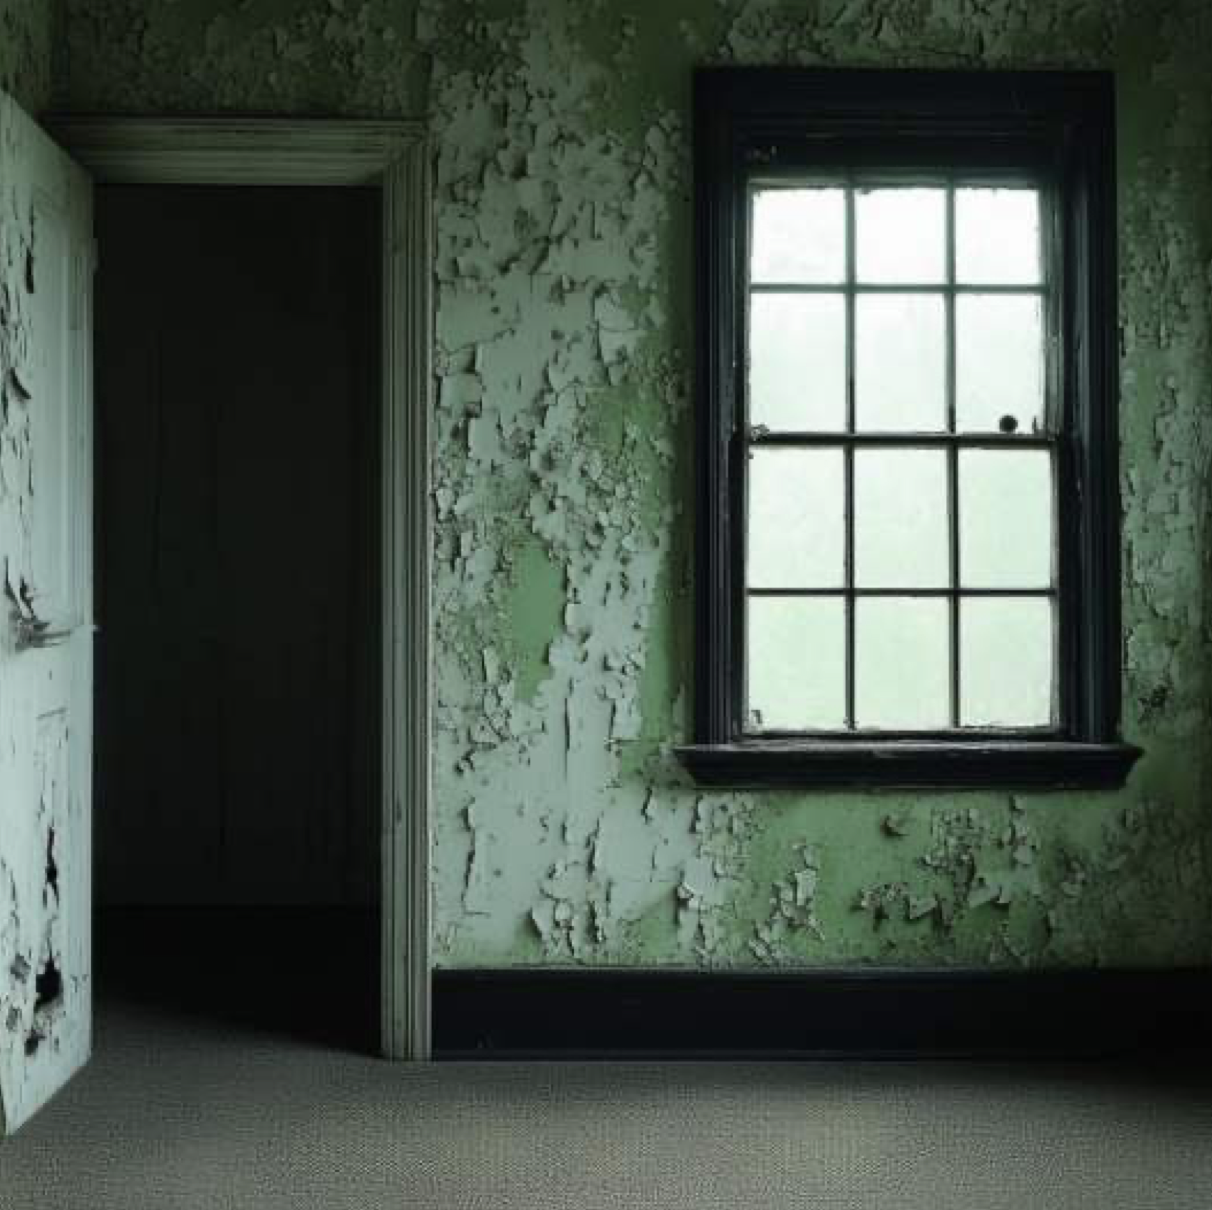 | PixMo-Cap |
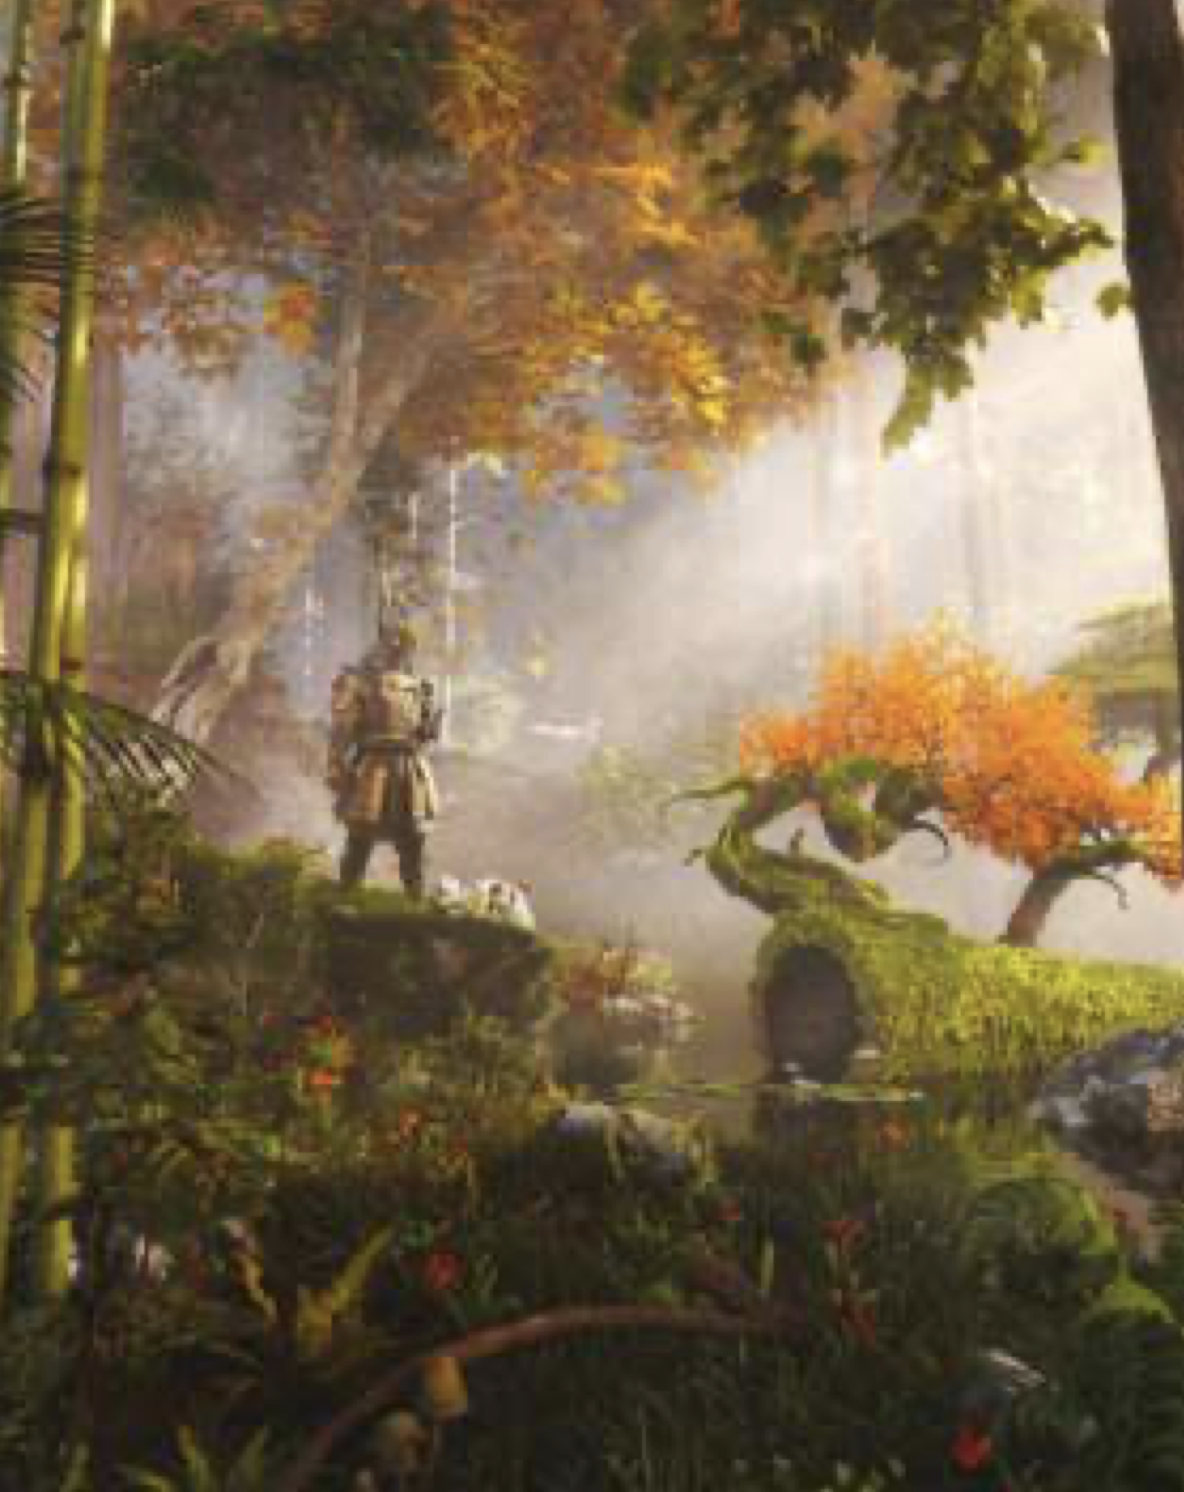 | PixMo-AskModelAnything |
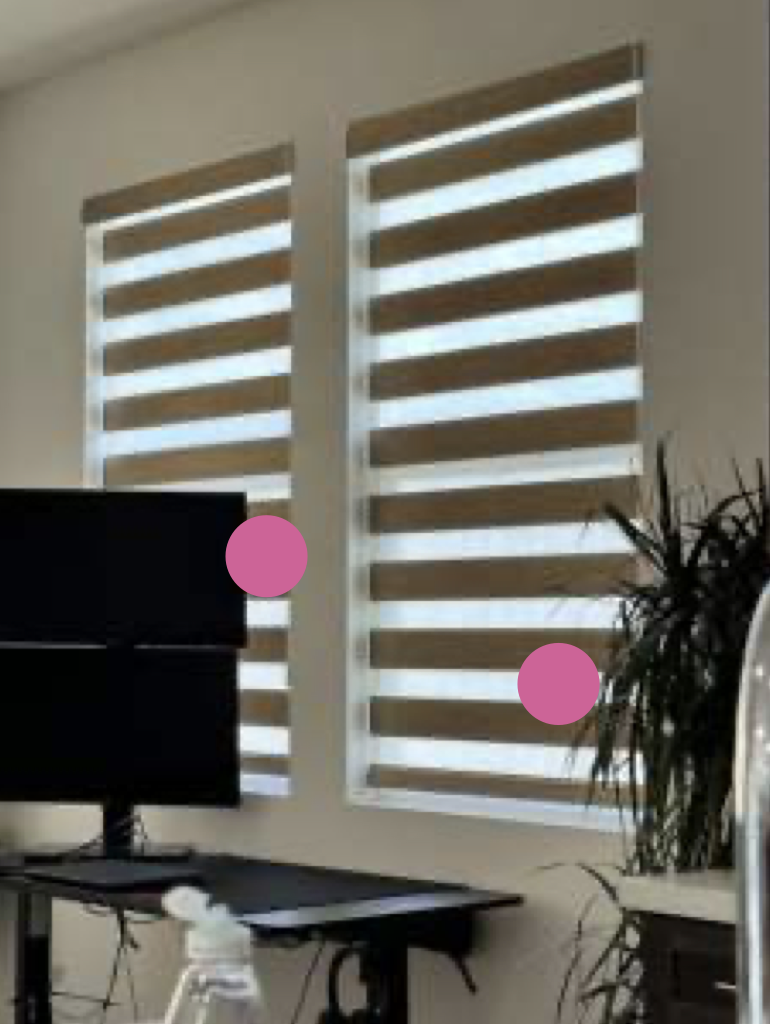 | PixMo-Points |
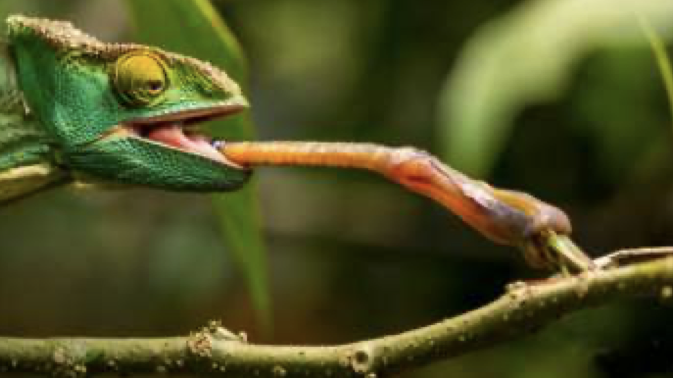 | PixMo-CapQA |
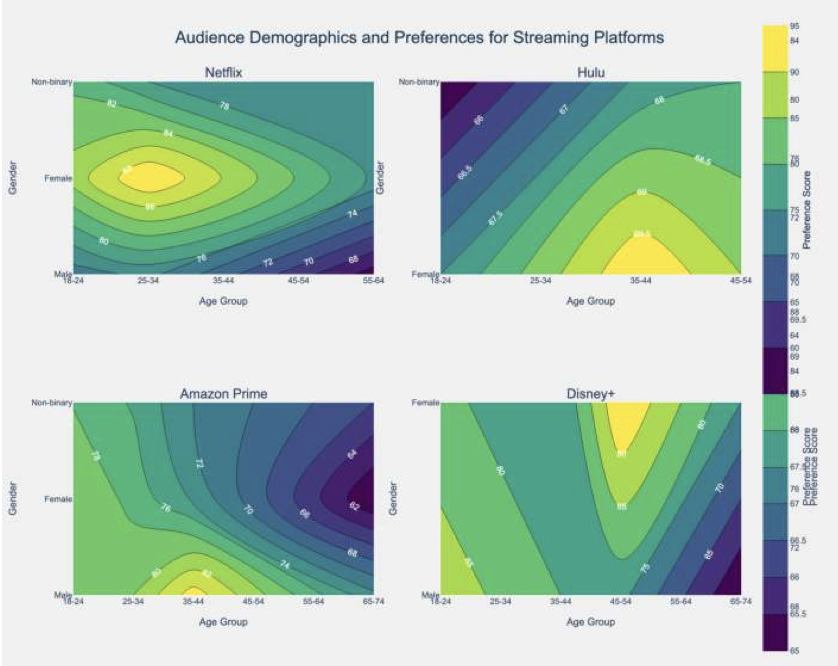 | PixMo-Docs |
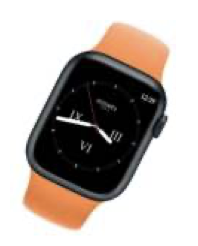 | PixMo-Clocks |
 | PixMo-Count |